What Is a Network Operations Center (NOC)? Daily Work, Shift Routine and a Handover Note Template
What a network operations center (NOC) does each day: monitoring scope, shift routine, alert handling, a handover note template and how a NOC differs from a SOC
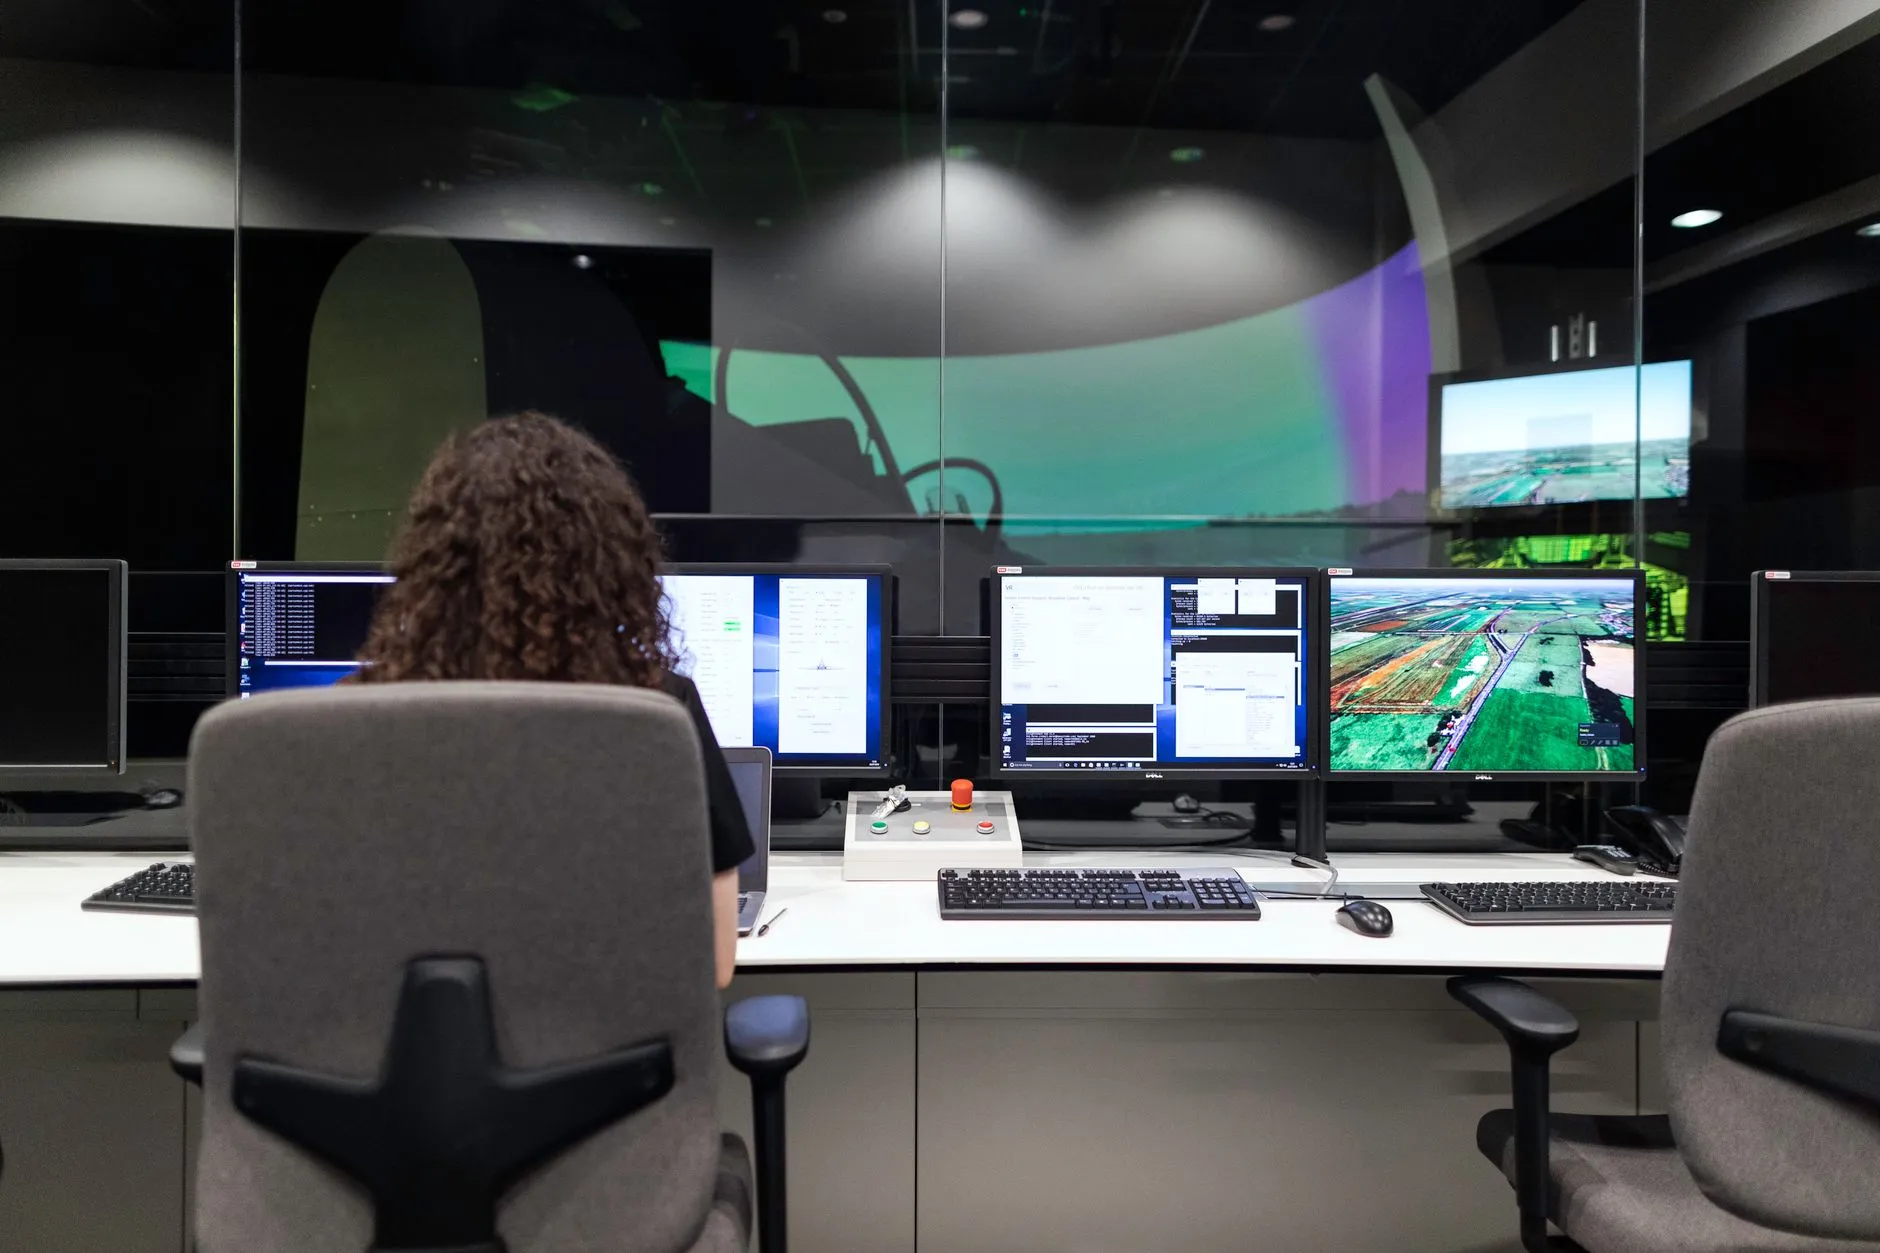
The short version: A network operations center (NOC) is the team and tooling that watch your network and infrastructure around a defined schedule, detect faults, fix or escalate them, and keep a record. A NOC protects availability and performance; a security operations center (SOC) protects against attacks. Both can exist in one organisation, and they need a clear route between them.
This is for IT managers deciding whether they need a NOC, and for anyone evaluating a provider's NOC service. You will get what a NOC watches, how a shift runs, a handover note template, escalation triggers to start from, and the differences between a NOC and a SOC.
What is a NOC?
Wikipedia's article on the network operations center (read 28 October 2026) describes it as one or more locations from which network monitoring and control is exercised over a computer, telecommunication or satellite network. NOC engineers deal with network failures, power outages and attacks that affect availability, configure equipment such as firewalls and routers, monitor activity, and keep the core network stable. Most work rotating shifts.
For a small or mid-sized organisation, "a NOC" usually means a service: a provider's team, tools and process that monitor your network and servers, handle alerts, and escalate to engineers. You do not need a room with large screens. You need coverage, a defined scope, and a process that works at 2 a.m.
What does a NOC do every day?
- Monitor the health of network devices, internet lines, servers, key services and backups.
- Triage alerts: decide which are real faults, which are noise, and which need action now.
- Diagnose and fix what can be fixed remotely: restart a service, fail over a line, clear a stuck interface, apply a configuration change under an approved procedure.
- Escalate faults that need a higher level, a vendor or an on-site visit, with a clear handover. See L1, L2 and L3 support levels.
- Communicate with affected users and the service owner at the agreed intervals.
- Record every alert, action and result in a ticket so the history is searchable.
- Handle planned work: maintenance windows, change checks before and after, and capacity watching.
- Report on availability, incidents and trends.
What does a NOC monitor?
Agree the scope in writing. A typical scope list:
- Network devices: firewalls, routers, switches, wireless controllers and access points, VPN gateways. Availability, interface status, utilisation, errors.
- Internet and WAN links: up/down, latency, packet loss, failover state.
- Servers and virtual hosts: online status, CPU, memory, disk, key services.
- Core services: DNS, DHCP, directory services, time sync.
- Backup jobs: success, age of last good backup.
- Power and environment: UPS state, room temperature where sensors exist.
- Cloud and application checks: website or login page responding, mail flow, Microsoft 365 service health (Microsoft 365 admin center > Health > Service health).
- Expiries: certificates, domains, support contracts.
For the threshold values to start from, read what to monitor and which alert thresholds to start with.
A shift routine you can copy
Adapt the times to your coverage hours.
Start of shift
- Read the previous shift's handover note (template below).
- Check the open ticket queue and any work waiting for a vendor or user.
- Check the monitoring tool itself: are all collectors and agents reporting?
- Check the planned maintenance and change calendar for today.
During the shift
- Work alerts in priority order. Acknowledge each one, so everyone knows it is being handled.
- For each alert, decide: false alarm (tune it later), event to record, or incident to work.
- For incidents, set the priority using your agreed rules; see severity vs priority in IT incidents.
- Update the ticket when you act, not afterward from memory.
- Escalate on the triggers below without waiting to be sure.
- Before and after any planned change, check the affected device and its neighbours.
Hourly or at set intervals
- Review the dashboard for amber items that are drifting toward red.
- Check the backup and job status for the period.
- Send the agreed updates on open incidents.
End of shift
- Close what is finished, with a short summary of cause and fix.
- Write the handover note.
- Hand over by message or call for anything critical; a note alone is not enough for a live incident.
Handover note template
Copy this into your ticket tool or shared document. Keep each line short.
- Shift and author: date, hours, who wrote it, who is receiving it.
- Open incidents: ticket number, one-line symptom, priority, current status, next action, and next update due.
- Alerts being watched: what, why it is not yet an incident, and the condition that would escalate it.
- Planned work: maintenance windows and changes in the next shift, with approver and rollback plan.
- Waiting on others: vendor case numbers, user replies, parts, with who chases and when.
- Changes made this shift: what changed, on which device, and who approved it.
- Known issues and workarounds: anything the next shift will otherwise rediscover.
- Monitoring health: tool or collector problems, silenced alerts and when the silence ends.
- Contacts in use: on-call engineers, vendor contacts, customer contacts for open items.
- Anything else the next shift must know: one line each.
Escalation triggers to start from
These are starting points to tune, not standards. Tie them to your SLA and escalation matrix; see the IT escalation matrix template.
- Time: an incident has no owner after 5 minutes, or no progress after 30 minutes for a critical one.
- Impact: more than one site or department is affected, or a core service (internet, authentication, mail) is down.
- Risk: any sign of an attack, data loss or unexpected configuration change goes to security immediately.
- Skill: the NOC has no documented procedure for the fault.
- Vendor: hardware fault or a bug that needs the maker.
- Major incident: meets your major incident criteria; switch to the major incident management process.
NOC vs SOC
Wikipedia's article on the security operations center (read 28 October 2026) says a SOC monitors an organisation's network, investigates potential security incidents, and takes the steps needed to remediate threats. It also notes a SOC can be internal or run by an outsourced security service provider. The practical differences:
Main question: NOC asks "is it up and performing?" SOC asks "is it safe, and is anyone attacking it?"
Typical alerts: NOC handles link down, high utilisation, failed backup, service stopped. SOC handles suspicious sign-ins, malware detections, unusual data movement, alerts from security tools.
Typical actions: NOC restarts, fails over, reconfigures, dispatches an engineer. SOC isolates a device, blocks an account, investigates, hunts for further activity.
Speciality skills: NOC needs networking and infrastructure skills. SOC needs security analysis and incident response skills.
Where they meet: an outage can be an attack, and an attack can look like an outage. Agree how each team hands cases to the other. For our security monitoring service, see security operations center.
How to tell whether a NOC service is any good
- Scope in writing: a list of monitored systems and the checks on each.
- Coverage hours: business hours or around the clock, and what happens outside them.
- Response targets: first response by priority; ours are published on the SLA page, and any provider's should be too.
- Escalation path: who is called, in what order, and by when.
- Reports: availability, incidents, alert volume, mean time to acknowledge and resolve; see MTTA, MTTR and MTBF.
- Change control: who may change what, and how changes are approved and recorded.
- Handover quality: ask to see a redacted example of a handover note.
Common mistakes
- Watching devices, not services. Everything is up and users still cannot work. Add service and login checks.
- No shared scope. Nobody knows whether the printer, the VPN or the Wi-Fi is in or out. Write it down.
- Alert fatigue. Too many low-value alerts hide the real one. Review alert volume monthly.
- Handover by memory. Verbal handover loses detail. Use the template.
- Fixing without recording. If a fix is not in the ticket, it will be repeated or contradicted.
- No route to security. Treat a suspected attack as a security case, not another network fault.
- Unmonitored monitoring. A silent collector looks like a quiet network.
How to check it worked
- Pick a monitored device and take it out of service in a maintenance window. Confirm the alert, acknowledgement and ticket arrive within your target.
- Read the last three handover notes. Could a stranger start the shift from them?
- Check that every incident in the last month has a cause, fix and owner recorded.
- Compare the alert count with the incident count. A large gap means tuning is overdue.
- Practise one escalation to a vendor or security so the contacts are known to work.
FAQ
What does a network operations center do?
It monitors networks and infrastructure, triages alerts, fixes or escalates faults, communicates with affected users, handles planned maintenance and records everything in tickets.
What is the difference between a NOC and a SOC?
A NOC keeps systems available and performing; a SOC detects and responds to security threats. They share data and need an agreed handover route.
What is the role of a NOC?
Its role is to keep services running by finding problems early, restoring service quickly and learning from repeat faults. It acts as the central point where alerts become tickets and tickets reach the right engineer. Day to day that means monitoring, alert triage, incident handling and escalation, change checks, communication, handover and reporting on availability and trends.
What do you need to run a NOC?
A defined scope, monitoring and ticketing tools, trained staff on a schedule that matches your coverage hours, written procedures, an escalation matrix, and handover and reporting routines. Small organisations usually buy this as a service instead of building it.
Next step
If you would rather have a team run this for you, start with the Brocent operation center page.
Sources checked 28 October 2026: Wikipedia, "Network operations center" and "Security operations center". Thresholds are starting points to tune.
Brocent publishes its managed IT support plans with per-user monthly prices for Hong Kong, Singapore, mainland China and the United States, so you can compare before you talk to anyone: see the plans and pricing.
Share:
Ready to take action?
Turn these insights into a roadmap for your business.
Book a 15-minute no-obligation consultation with our APAC IT experts. We'll review your current setup and provide a tailored IT roadmap within 24 hours.
Related services
Free Checklist
10 Critical Checks Before Expanding IT to Greater China
PIPL compliance, network segmentation, bilingual helpdesk setup, and more — everything your IT team needs before Day 1 in China.
Request the checklist →📬 Monthly Asia IT Insights
China compliance updates, cybersecurity alerts, and IT tips for APAC teams — once a month.
No spam. Unsubscribe anytime.
Related Articles
Oct 30, 2026
Remote Monitoring: What to Monitor and Which Alert Thresholds to Start With
Oct 30, 2026
Network Mapping and Documentation Template: Topology, IP Table, VLANs and Device Inventory
Oct 30, 2026
Network Firmware Upgrade Checklist: Switches, Firewalls and Access Points, Step by Step