Hypercare IT Support in Hong Kong: Who Fixes the Printers and Scanners When the ERP Goes Live
A ninety-person Hong Kong trading company cuts over to a new ERP over one weekend, and nobody owns the printers, scanners and permissions around it. This guide explains what hypercare IT support covers, how to size it, what the first 72 hours look like and how it ends. It is an illustrative composite scenario, not a named client.
Most go-live problems on Monday morning are not ERP defects. They are label printers, scanner drivers, permissions and people who cannot find the new screen. Hypercare IT support in Hong Kong puts engineers on the floor for a fixed window, tightens monitoring, opens a direct escalation line and ends with a written handover to normal support.
The company, and the weekend everything changes
Picture a Hong Kong trading and distribution company with about ninety staff. It imports consumer and light industrial goods from suppliers in Mainland China and Southeast Asia and sells to retailers, contractors and online sellers. The people are split across three places. A sales and finance office sits on one floor of a commercial building, and a warehouse occupies part of an industrial building in Kowloon East or Kwai Chung. A handful of buyers travel to supplier factories across the border and work from laptops and phones.
For eleven years the business has run on an old accounting package, a stock spreadsheet that has quietly become a system of record, and a set of order forms that live in shared mailboxes. Month-end takes the finance team nearly a week because every figure has to be reconciled by hand. The finance director has finally signed off a new ERP, an integrated platform that handles orders, stock, purchasing and the ledger in one place. An implementation partner has been engaged. The cutover is planned for a weekend: freeze on Friday evening, data migration overnight, validation on Sunday, and everybody logging in to the new system on Monday morning.
This article is written for the person who sponsors that project, usually the finance director, sometimes the operations director. One clear note before going further: this is an illustrative composite scenario, not a named client. It is built from the shape of a situation that is common among Hong Kong trading and distribution firms, and every number about the company itself is an assumption chosen to make the arithmetic readable.
The company has one internal IT person. We will call him the IT officer. He is good, he knows every laptop and every password, and he is already saturated by a normal week. In the project plan, nobody wrote down who would help him on Monday.
That omission is the subject of this article. The ERP will mostly work. The question is who looks after everything around it while ninety people learn a new way of doing their jobs at the same moment.
Who fixes what when the ERP goes live?
Start with a simple observation. A go-live is not one event. It is a long list of small events that all happen in the same few days, and they belong to different owners.
What the ERP implementer is responsible for
The implementation partner is responsible for the ERP itself. That means configuration, data migration, the accuracy of the chart of accounts, the workflows, the reports, the training of key users, and defects in the application. When a purchase order calculates tax wrongly or a stock movement fails to post, that is the implementer's problem, and a good partner will have people ready for it.
The contract is typically written around that scope, and for good reason. The implementer cannot be responsible for the company's laptops, the warehouse Wi-Fi or a label printer bought five years ago. They did not choose those things, they cannot see them, and their staff are often not in Hong Kong during the go-live window.
What nobody owns on the floor
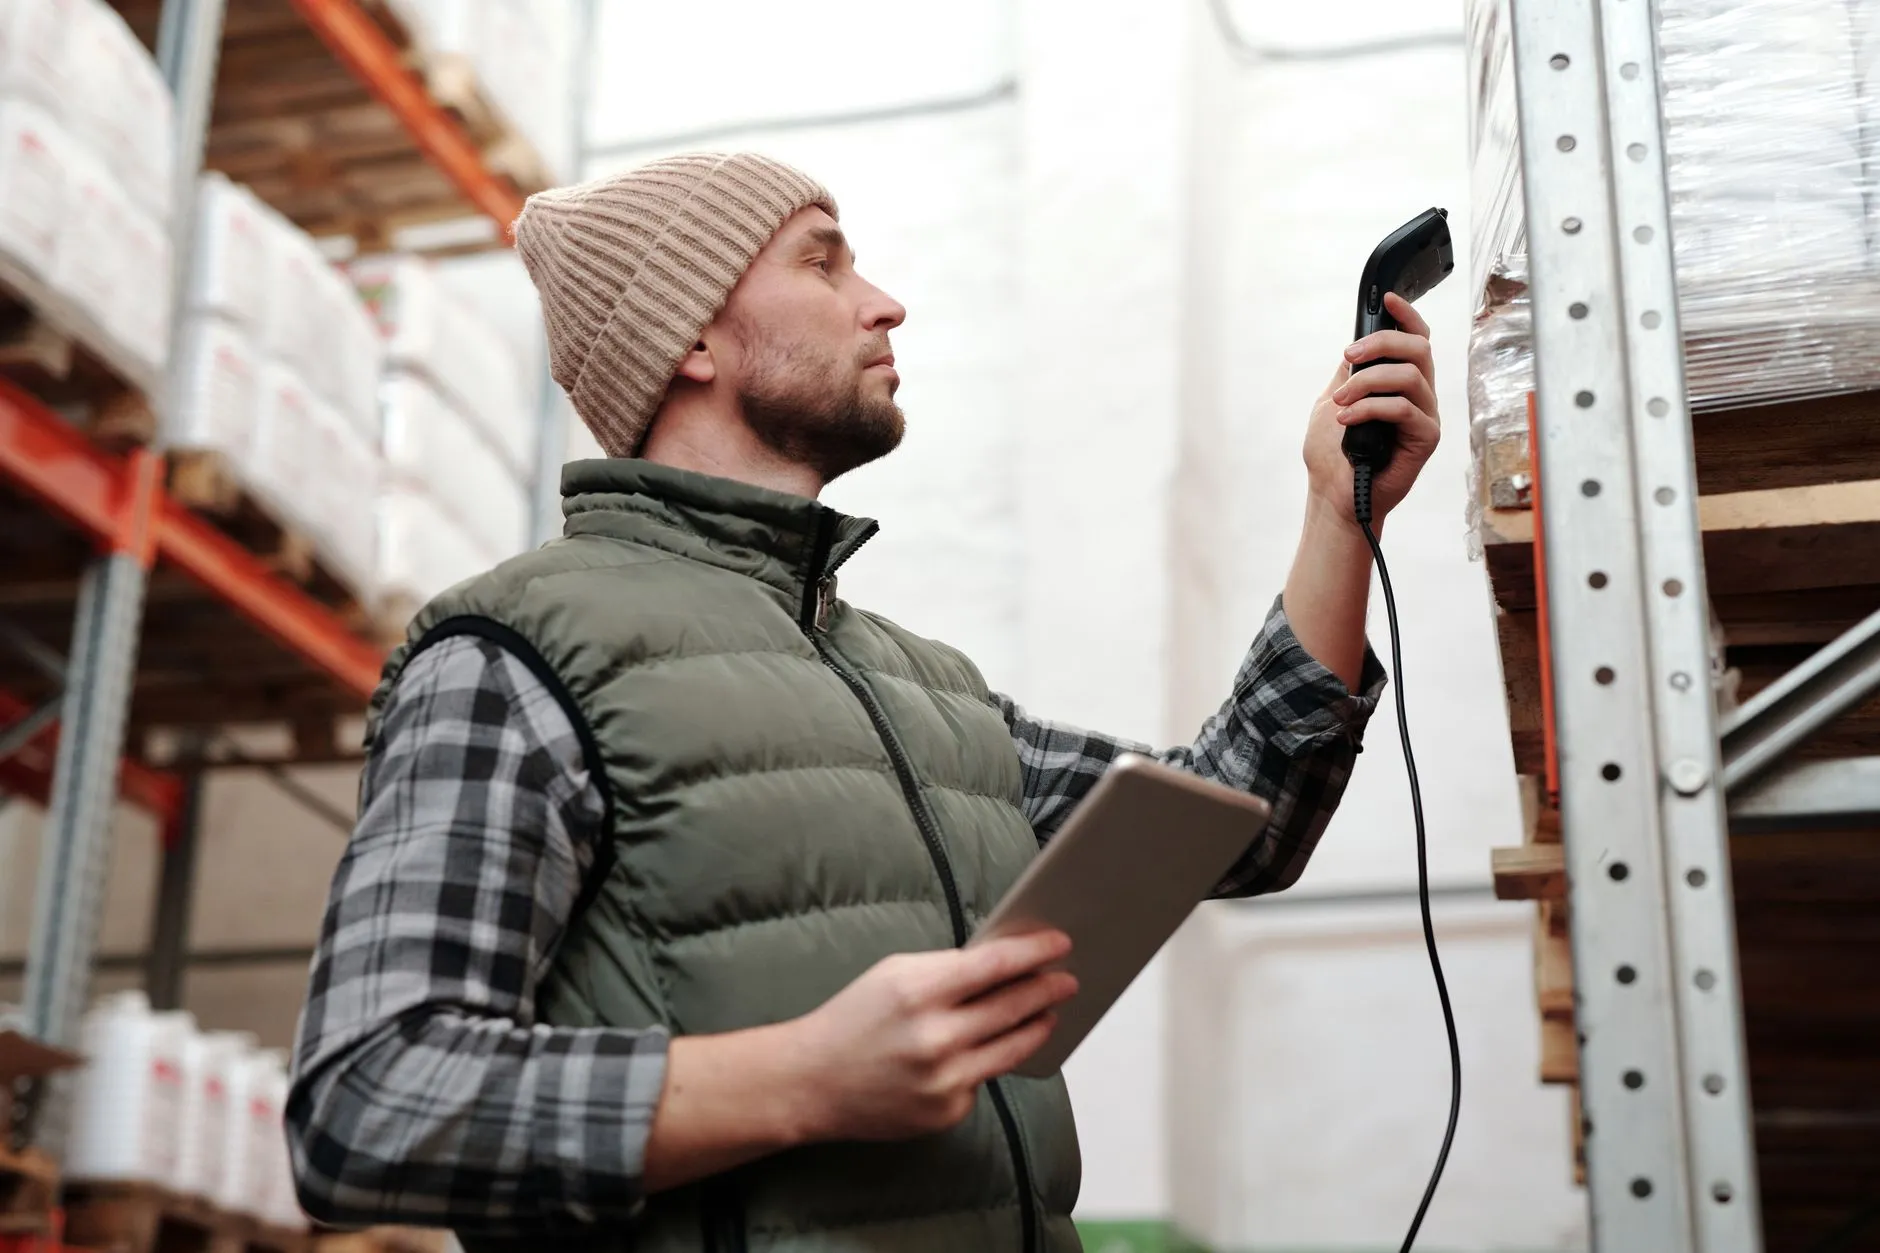
Now list what happens on a real Monday morning in the warehouse and the office. These are the kinds of issues that surface:
- A label printer in the warehouse prints the old format, because the driver was never updated for the new label template.
- Handheld scanners connect to the Wi-Fi but cannot reach the new system, because a firewall rule or a certificate was not part of the project checklist.
- Six people in finance can open the new system but cannot see the ledger screens. Their roles were mapped from a spreadsheet that was out of date.
- The sales team's laptops open the old shared drive by habit, so people keep saving files in the wrong place.
- A single sign-on prompt loops for one user because of a browser setting, and she cannot reach the login page at all.
- The bank connection or a courier integration that ran quietly before now needs a new credential, and the person who holds it is on leave.
- A user clicks on the old shortcut, finds nothing, and tells the office manager that the system is down.
None of these is an ERP defect. Almost all of them look like ERP defects to the person standing in front of a stuck screen, so they arrive as one undifferentiated flood of complaints. The finance director sees "the ERP is down" and phones the implementer, who has to spend time proving that it is not.
The gap that causes the damage
This is the gap between the implementer's scope and everything else on the floor. It is nobody's fault. It is a mismatch between how a project is organised, around a system, and how a go-live is experienced, around a person trying to do a job.
Internal IT is the only team that spans both, and it is the team with the least spare capacity. The IT officer is simultaneously the project's technical contact, the person who answers when a user is stuck, the person who must keep the rest of the business running, and the person who has to explain to the board what is going wrong. Our scenario company's IT officer has been writing a cutover checklist at night for two months. By Monday at 10 a.m. he will have been interrupted forty times.
If this sounds like your project, the useful framing is not "do we need more IT". It is "for a defined window, who is physically on the floor, with authority to fix things, and who does the IT officer call when he needs a second pair of hands".
What is hypercare IT support?
Hypercare is a short, intensive support engagement wrapped around a high-stakes event such as an ERP go-live, a major technology rollout or a new office opening. Brocent describes it on its Hypercare IT support service page as a time-boxed engagement in which experienced engineers are physically embedded at your site during the critical window. This section sets out what that service page states, in plain terms.
On-site engineers working beside your users
Engineers work shoulder to shoulder with staff during the go-live window and resolve issues on the floor, in real time, before they grow into incidents that delay the launch. In our scenario this is the label printer and the scanner problem. Someone is standing next to the person who has the problem, and the fix happens in minutes rather than after a ticket has travelled through a queue.
Tighter monitoring for the period
Monitoring thresholds are tightened for the hypercare period. According to the service page, that means faster polling intervals, lower CPU and memory baselines, and immediate paging for any anomaly, not only the critical ones. The reasoning is simple. In normal operation an alert that fires after ten minutes of high load is sensible. During a go-live, ten minutes of slowness is the whole story, because everyone is trying the new system at once.
A direct escalation line
A dedicated line, by phone and chat, connects your operations team to Brocent senior engineers and management, with no queue and no menu. The service page describes it as available around the clock for the hypercare window. This matters because the awkward problems tend to appear at the edges of the day: Sunday night during validation, or 7 a.m. on Monday before the office is full.
A war room
Brocent sets up a virtual or on-site war room during the go-live, with the relevant engineers and your stakeholders in one communication channel, so coordination and decisions happen in one place. For a company with an implementation partner abroad, a finance director, a warehouse manager and an IT officer, a single channel is more valuable than it sounds. It stops the same fault being reported three different ways to three different people.
Daily briefings and a structured ending
Daily hypercare briefing reports cover incidents raised, resolved and in progress, so the project sponsor can see the health of the go-live without asking. And hypercare ends with a formal handover: a full incident log, a lessons-learned document, a known-issues register, and confirmation that normal monitoring and escalation paths are live and tested. We return to the ending below, because it is the part that is most often skipped.
What the service page does not say
The page does not state a day rate, a package price or a standard duration. It describes a four-step flow, which is scope and briefing, engineer deployment, active hypercare and transition to business as usual, and it says the window, the systems in scope, the user count and the risk areas are defined at the first step. This article follows that approach. Where we give sizes or durations below, they are the assumptions of the illustrative company, not Brocent's published figures.
How many engineers, for how many days, on which shifts?
Sizing is where hypercare decisions are usually made badly, either by over-buying out of fear or under-buying to keep the budget line small. The better method is to work from the shape of the demand.
Start from the people and the places
Demand is not spread evenly. It concentrates in two places: wherever people are using the new system for the first time, and wherever hardware touches it. For our company that means the warehouse floor, where scanners, label printers and shared terminals are used by people who are not used to desk work, and the finance office, where the permissions and the ledger are used by people who are very used to desk work and will notice every error.
The company has about ninety people. Perhaps sixty of them use the system every day and thirty only occasionally. Those are the assumptions we will carry through the example.
A worked example, clearly labelled as an assumption
The sizing below is the illustrative company's, not a rule from Brocent. It is how a sensible plan might look for a ninety-person business with two sites.
- Warehouse: one engineer for the first three working days, because it is the site with the most physical equipment and the least tolerance for a stoppage. After that, an engineer visits for a short window each day.
- Office: one engineer for the first three working days, covering finance, sales and the shared devices. After that, the engineer splits time between the office and the warehouse.
- Escalation line and monitoring: active for the whole window, so the in-office engineers can pull in senior help for anything unusual.
- The IT officer: protected. He remains the owner of the company's systems and is not asked to run the floor. The engineers take the queue, and he takes the decisions.
This is two engineers for the first three working days, then one, with senior cover available remotely throughout. It is a starting point for a conversation, not a recommendation. Your own number depends on how many sites you have, how many users change what they do on day one, how many pieces of physical equipment depend on the new system, and how much remote capability you already have.
How long should the window be?
Two things set the length. The first is the adoption curve. Support demand is highest on the first day and drops as people learn the screens. The second is the first month-end close, which is the moment the ERP is tested for real. A window that ends before the first close leaves the finance team alone at the moment they most need help.
In the scenario, a reasonable plan has heavy on-site presence for the first three working days, lighter presence for the rest of the first fortnight, and elevated monitoring and the escalation line running until the first close has been completed. That is a judgement for this fictional company. For yours, the scoping step exists to make this decision with evidence rather than guesswork.
Which shifts?
Match shifts to when people actually work. A warehouse that starts loading at 7 a.m. needs an engineer on site before that, not at 9. A finance team that works late on the evening of the first close needs a reachable engineer in the evening. The escalation line covers the hours the engineers are not physically present.
Hong Kong adds one more consideration: bilingual coverage. The warehouse supervisor is more comfortable in Cantonese, the implementer's consultants work in English, and the supplier contacts in Mainland China use Mandarin. Engineers who move between those without friction save time that is hard to measure but easy to feel.
What do the first 72 hours look like?
Here is the plan for our scenario, hour by hour. The details are the illustrative company's, but the order of the work is typical of a cutover that lands on a weekend.
Friday evening to Saturday: before anyone logs in
The engineers arrive before the freeze, or connect to the war room channel if they are working remotely at this stage. They are briefed on the cutover plan and the list of in-scope systems. Monitoring thresholds are tightened. The escalation line is confirmed with a test call, and the war room channel is created with the implementer, the finance director, the warehouse manager and the IT officer in it.
The first useful job is a physical inventory of everything that touches the new system: every scanner, every label printer, every shared terminal, every laptop assigned to a key user. It is boring work, and it is exactly the work that the project plan assumed somebody had done.
Saturday: migration night and the first test
While the implementer migrates the data, the on-site engineer tests every device against the staging or test environment, checking that each scanner reaches the system, each printer prints the new label, and each key user can sign in. Anything that fails is noted, fixed and retested. A scanner that cannot connect on Saturday is an inconvenience. The same scanner failing on Monday at 7 a.m., with a truck waiting at the dock, is an incident.
Sunday: validation, with a safety net
Key users validate their own screens, and this is where the permissions problems appear. The finance team cannot see the ledger screens. The warehouse supervisor cannot approve a stock transfer. Each is logged in the war room, assigned to the right owner (the implementer for role mapping, the engineers for devices and access) and closed before the end of the day.
By Sunday evening the engineers hold a short readiness review with the project sponsor. It lists what is ready, what is known to be open and what the workaround is for each open item. No surprises is the rule.
Monday, 7 a.m. to 10 a.m.: the peak
This is when the plan is tested. The engineers are on the floor before the first shift. The warehouse engineer is standing by the receiving dock. The office engineer is in the finance area. Both are in the war room channel.
The most common calls in this window are the ones from the list earlier: a user who cannot find the screen, a device that has dropped off the network, a permission that is wrong. They are fixed on the spot. Anything that is actually an ERP defect is passed to the implementer with the evidence already collected, so the implementer spends time on the defect rather than on proving that it is not a network fault.
Monday midday to Tuesday: the long tail
The first morning's rush passes and a different pattern emerges: people who got through the morning on instinct now hit the second layer of problems. A report that will not export. A scanned document attached to the wrong record. An integration with the courier that needs a fresh credential. The daily briefing at the end of the day lists what was raised, what was resolved and what remains open. The finance director reads it and sees that the number of open issues has fallen, rather than hearing about it from a worried colleague.
By Tuesday evening the shape is usually clear. If the plan was right, demand is already falling, the engineers are doing less firefighting and more teaching, and the open items are a short and well-understood list.
Implementer support, internal IT alone, or a hypercare engagement?
There are three realistic ways to cover a go-live. This is how they compare on the questions that matter to the sponsor: who fixes what, for how long, and what is left at the end.
The ERP implementer's post-go-live support
- Who fixes what: the ERP application, including configuration, data defects, workflows and reports. Devices, networks, printers and user access outside the application are generally outside the contract.
- How long: whatever the contract says, often a defined period after go-live, and usually delivered remotely, with limited time on site.
- What is left at the end: a stable application and a list of open defects. The implementer's records cover the ERP and nothing else.
- Best suited to: application problems. It is the right owner for them, and it should be kept in the loop either way.
Internal IT alone
- Who fixes what: everything, in theory. In practice, whatever the IT officer reaches first, in the order that the loudest person asks.
- How long: as long as it takes, which means the IT officer's evenings and weekends.
- What is left at the end: a very tired IT officer, no independent record of what happened, and a risk that the knowledge leaves with him if he resigns.
- Best suited to: small cutovers with a handful of users, where the IT officer genuinely has spare capacity and the go-live does not touch much physical equipment.
A hypercare engagement
- Who fixes what: the floor, meaning devices, printers, scanners, access, connectivity, user guidance and monitoring, with a clear line to the implementer for application defects.
- How long: a defined window, agreed at scoping, with a defined end.
- What is left at the end: the formal handover pack, with the incident log, the known-issues register and the lessons-learned document, and confirmation that normal monitoring and escalation paths are working.
- Best suited to: a go-live that touches many users and many devices at once, where internal IT is already full.
The three are not alternatives to each other so much as three layers. The implementer owns the application, internal IT owns the company's systems, and hypercare is the temporary extra capacity that lets both do their jobs during the weeks when the load is highest.
When does hypercare end?
A support window that has no end is not hypercare. It is an unplanned outsourcing arrangement, and it is usually more expensive than a planned one. Agreeing the exit criteria before the go-live is what keeps the engagement short and honest.
Exit criteria worth writing down
Criteria are specific to the company, but a good set looks like this:
- No open incident above an agreed severity, and no unresolved issue that stops a business process from running.
- Daily incident volume has been below an agreed level for several consecutive working days.
- The first month-end close, or the equivalent first full business cycle, has completed without a floor-level blocker.
- Normal monitoring is live, its alert thresholds are back to standard values, and a test alert has reached the right person.
- The business-as-usual escalation path has been tested end to end, not simply documented.
- The sponsor has read the final briefing and agrees the remaining items are acceptable.
The list should be agreed in writing, so that the decision to stand down is a check against criteria rather than a negotiation.
The handover pack
The service page lists what the transition contains, and it is worth treating as a checklist.
- The incident log: every issue raised, how it was resolved and how long it took. In a year's time it will explain why a setting is the way it is.
- The known-issues register: what is still open, who owns it, and what the workaround is.
- The lessons-learned document: what the go-live revealed about the environment, the training and the process, written down while it is fresh.
- Confirmation of business-as-usual support: monitoring and escalation paths live and tested, so that the day after the engineers leave, someone knows who to call.
The point of the pack is that the knowledge belongs to the company. If the IT officer resigns six months later, the account of what happened during the go-live is not in his head.
What does hypercare cost compared with a delayed month-end close?
We are not going to quote a price, because Brocent's hypercare page does not publish one and a price depends on the scope. You can get one from a scoping conversation, and Brocent's pricing page shows how it publishes rates where it does. What is more useful here is how to weigh the cost.
Compare it with the cost of a bad first month, using your own numbers. Ask five questions:
- If the warehouse cannot dispatch for half a day, what is the value of the orders that slip?
- If the first month-end close takes two weeks instead of one, what does that cost in finance time, and what decisions wait on the numbers?
- If the finance director spends the first week as the project's complaints desk instead of running finance, what is not being done?
- If your IT officer burns out or leaves after the go-live, what does it cost to replace him and recover what he knew?
- If customers receive late or wrong deliveries during the first week, what is the cost to the relationships?
You will not have precise answers, and you do not need them. If any one of those costs is plausibly larger than a short, scoped engagement, the decision is already clear. If none is, you probably do not need hypercare, and a lighter arrangement may be enough.
That second possibility is worth taking seriously. A go-live with fifteen users, no physical equipment and a well-staffed internal IT team may not need an embedded engineer. Hypercare is for the case where the load is high and the margin for error is low.
Hypercare is a spike. What does the floor run on afterwards?
The most important sentence in the handover is not about the engineers leaving. It is about what is in place the day after they have gone.
Hypercare is deliberately temporary. It raises the level of support for a few weeks. After that, the floor needs a steady model that matches how much IT the company actually uses, and the go-live will have given you good evidence about that. The incident log shows which problems keep recurring, which sites generate the most calls and what hours the demand falls in.
There are three common destinations:
- A scheduled and on-demand model. For a company whose IT is modest, regular visits plus remote help may be enough. A separate article on onsite IT support models in Hong Kong compares the embedded, scheduled and dispatch patterns.
- A dedicated engineer. If the incident log shows that a warehouse and an office generate enough work to keep one person busy, Brocent's full-time onsite IT support provides a named engineer, with cover for leave and backing from Brocent's wider team.
- A help desk behind the IT officer. If the pressure is outside normal hours, the 24 x 7 help desk answers in Mandarin, Cantonese and English, and Brocent publishes around 15,000 incidents handled each year, with 90% of calls answered within 40 seconds.
These are not mutually exclusive. They are folded into a single arrangement under managed IT support, which is where most companies that have been through a hypercare window end up, because they have just discovered how much invisible work their one IT person was doing. Brocent, founded in 2007 and headquartered in Singapore, has run a permanent engineering office in Kwun Tong, Hong Kong, since 2016.
Frequently asked questions
How long should hypercare last?
There is no published standard, and the Brocent service page does not give one, because the window is defined at scoping from your go-live plan. Two things usually set the length: how quickly demand falls after the first days, and when the first full business cycle, such as the first month-end close, completes. In our illustrative company that meant heavy on-site presence for three working days, lighter presence for the rest of the fortnight, and monitoring and the escalation line running until the first close was done. Agree the exit criteria in writing before go-live.
Is hypercare only for ERP projects?
No. Brocent describes hypercare as suited to ERP go-lives, major technology rollouts, new office openings and high-stakes business events, and the service page lists ERP, Microsoft 365, office openings and cloud migrations among the cases it covers. The common thread is a short period in which many people and systems change at once, and a cost of failure that is high.
Does the ERP vendor or implementer provide this?
Usually not for the floor. The implementer is responsible for the application: configuration, data, workflows and defects. Devices, printers, scanners, networks and access outside the application are generally outside that scope, as you can confirm in your own contract. Some implementers can recommend or coordinate a partner for it. The practical step is to ask the implementer, in writing, exactly what their post-go-live support includes and what it does not.
How many engineers do we need for 100 users?
It depends more on the sites and the equipment than the headcount. A hundred people at one desk-based office is a different problem from a hundred people split between an office and a warehouse full of scanners and printers. In our illustrative ninety-person company the plan was two engineers for the first three working days, then one, with senior cover remotely throughout. That is an assumption for the example, not a rule. The scoping step is where the number should be set, using your user count, your sites and your risk areas.
Can hypercare be done remotely?
Partly. The service page says engineers are on site, or connect to virtual channels, and that the war room can be virtual or on site. Remote monitoring, the escalation line and the war room work well remotely. What a remote engineer cannot do is replug a device, replace a cable, stand next to a user and show them the screen, or fix a scanner at the loading dock. For a go-live with physical equipment, on-site presence for the first days is usually worth having, with remote support for the rest.
What happens to issues still open when hypercare ends?
They go into the known-issues register, which is part of the handover. Each entry has an owner and a workaround, and the register is handed to whoever provides business-as-usual support. A problem that is open at the end of the window should never be a surprise to the sponsor, because the daily briefings have been listing it for days.
Can we extend hypercare?
Yes, by agreement, and it is better to decide that against the exit criteria than to drift. If the criteria are not met, because the first close has not completed or a persistent problem remains, an agreed extension for a defined period is sensible. An extension that has no end date is a signal that the right answer is a different, steady support model.
Where to go from here
If your ERP go-live is on the calendar, start by writing down three things: the date and the systems in scope, the number of users and sites, and the physical equipment that depends on the new system. That is most of what a scoping conversation needs.
From there, re-read the Hypercare service description, and then contact the Brocent team with the date and the shape of the cutover. Ask for a scoped proposal that includes the window, the staffing, the exit criteria and the handover pack, so you can compare it with the cost of a bad first month.
Share:
Ready to take action?
Turn these insights into a roadmap for your business.
Book a 15-minute no-obligation consultation with our APAC IT experts. We'll review your current setup and provide a tailored IT roadmap within 24 hours.
Explore all servicesFree Checklist
10 Critical Checks Before Expanding IT to Greater China
PIPL compliance, network segmentation, bilingual helpdesk setup, and more — everything your IT team needs before Day 1 in China.
Request the checklist →📬 Monthly Asia IT Insights
China compliance updates, cybersecurity alerts, and IT tips for APAC teams — once a month.
No spam. Unsubscribe anytime.
Related Articles
Sep 22, 2026
Embedded, Scheduled or Dispatched: Choosing an Onsite IT Pattern for a Hong Kong Office of 40
Aug 07, 2026
IT Support Hong Kong: One Contract for Cross-Border Teams
Sep 01, 2026
The Building Is the Bottleneck: IT Support in a Kowloon East Industrial Block