Service Request vs Incident: Three Questions to Tell Them Apart, With 20 Examples
Service request or incident? Use three decision questions, 20 classified examples and the different handling flow for each, so tickets reach the right queue.
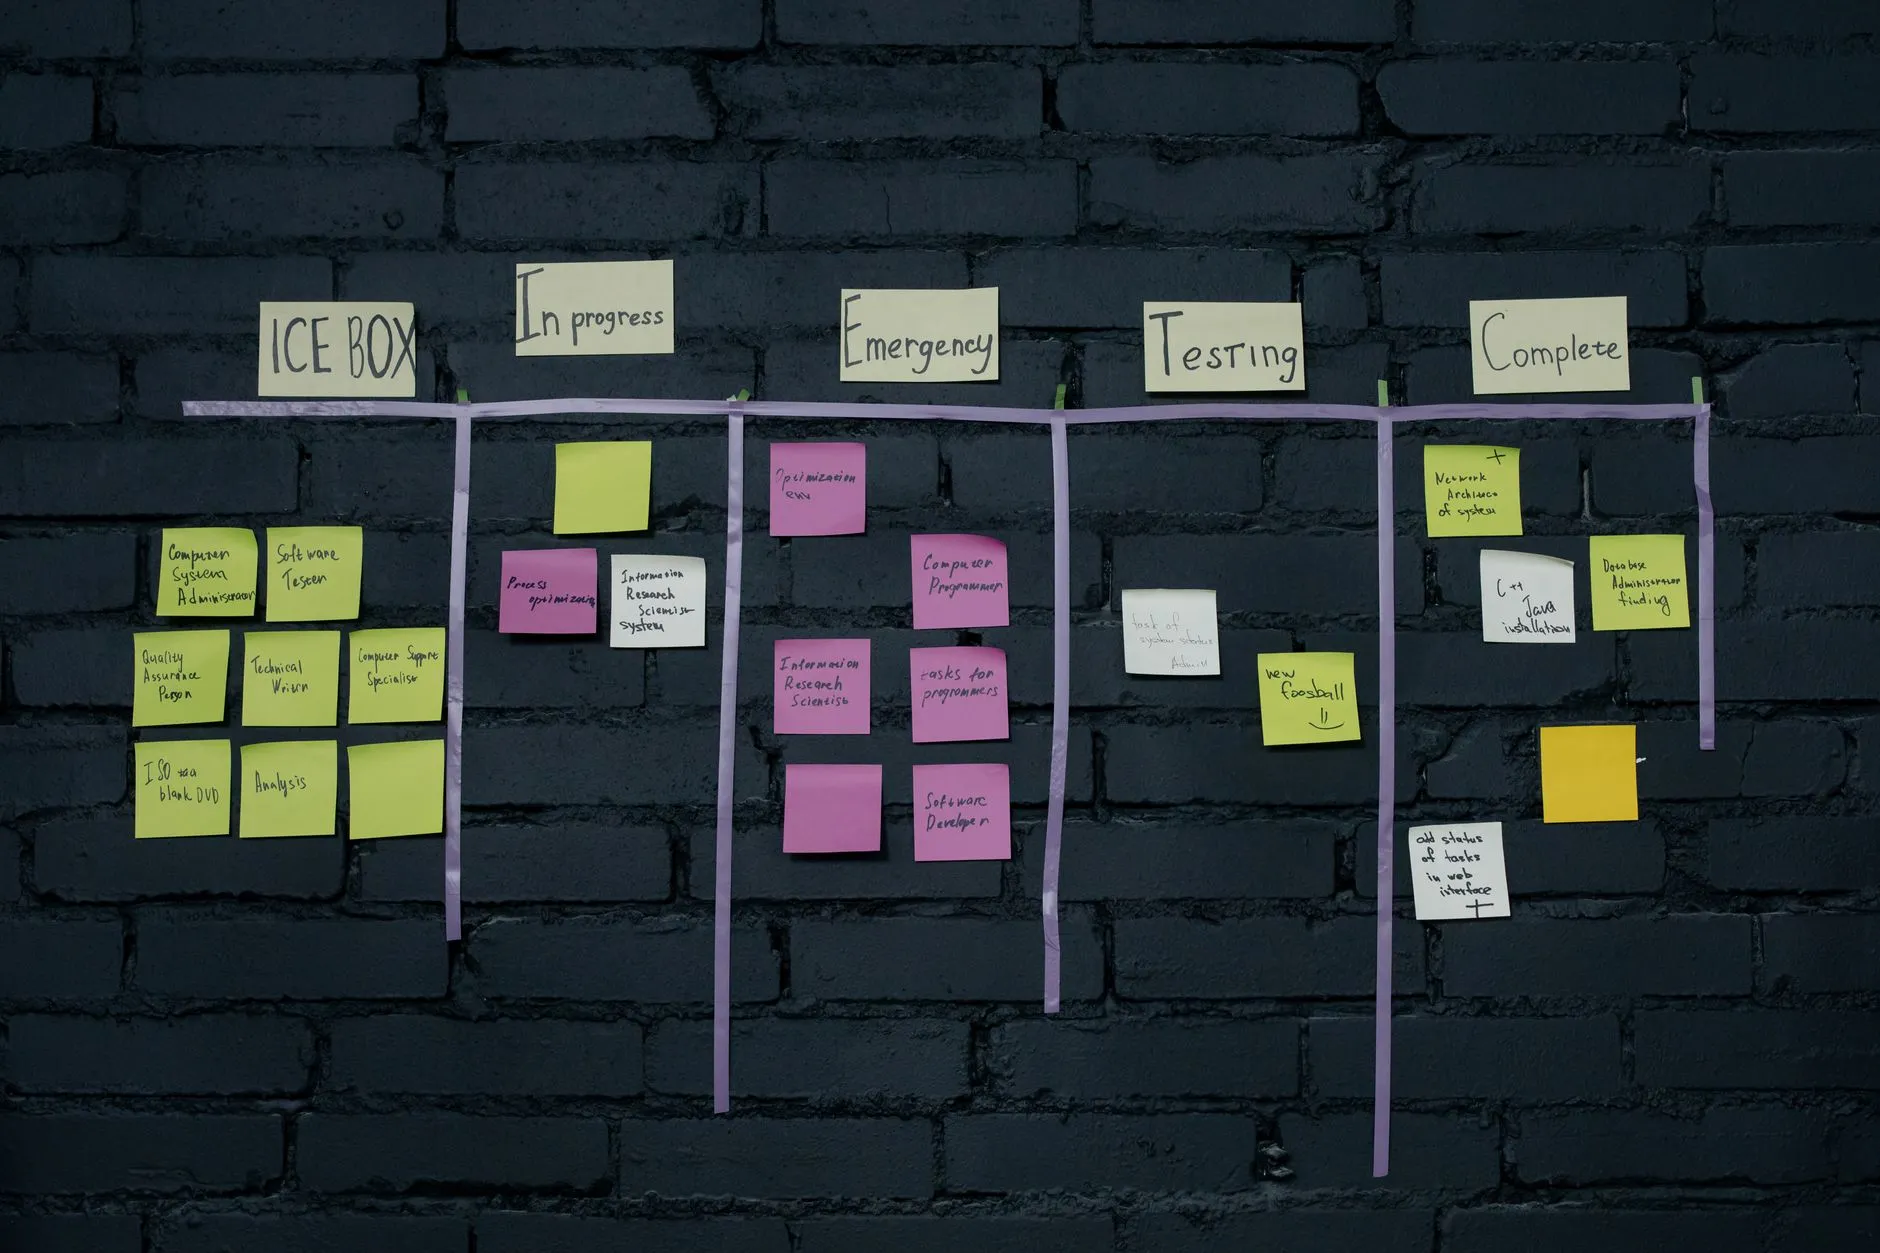
The short version: An incident is something that worked and now is broken or degraded. A service request is a user asking for something your service catalogue already offers as a normal, repeatable service. Incidents are about restoring service as fast as possible. Requests are about delivering an agreed item on an agreed timeline, usually with an approval step. When you cannot decide, ask the three questions below in order.
This guide is for service desk leads, IT managers and anyone who sets up a ticketing tool. After reading it you can sort any ticket into the right type in under a minute, use 20 worked examples to train new staff, and set up two different handling flows so requests stop being treated like emergencies.
What is the difference between a service request and an incident?
ITIL 4 defines a service request as a request from a user, or the user's authorised representative, that starts a service action which has been agreed as a normal part of service delivery. It defines an incident as an unplanned interruption to a service, or a reduction in the quality of a service (checked 28 October 2026).
Put simply:
- Incident: "It was working. Now it isn't, or it is worse than before."
- Service request: "I need something that you already have a standard way of giving me."
The difference matters because the two are measured and handled differently. An incident clock measures how fast service is restored. A request clock measures whether the item was delivered by the agreed date. Mixing them hides real outages inside a pile of routine work, and it makes routine work look like firefighting.
The three decision questions
Ask these in order and stop at the first "yes".
- Was something working before that is now broken, slow or unreliable? If yes, it is an incident, even if the user phrased it as a request ("please fix my email").
- If nothing is broken, is the thing asked for in your service catalogue, or covered by a standard procedure? If yes, it is a service request. This includes access, new equipment, software installs, account changes and "how do I" questions.
- If it is neither, is it a change to the environment or something new? Then it is a change request (or a project), which needs assessment before work starts. Anything where the cause of repeated incidents is unknown is a problem record, linked to the incidents.
Two tie-breakers help with edge cases:
- Look at what the user needs, not the words they used. "I can't open the finance share" could be a permission that was never granted (request) or a share that went down (incident). Check whether it ever worked for this user.
- Classify by the first need. If a request fails during fulfilment, keep the request open and raise an incident against the failure. Do not quietly convert one into the other.
20 classification examples
Incidents (8)
- Outlook cannot connect since this morning: it worked yesterday, so service is interrupted.
- The shared printer prints blank pages: quality of a working service has dropped.
- Wi-Fi drops every few minutes in the meeting room: degraded service. Link repeated reports to one parent incident.
- A laptop blue-screens at start-up: a hardware or operating system failure.
- VPN connects but internal file shares are unreachable: part of the service is down.
- Teams calls have no audio for one user: service interrupted for that user. If it hits many users, raise it as a higher-priority incident.
- The internal web application shows an error page: service outage for everyone who uses it.
- The overnight backup job failed: a failed service that users may not notice yet. It is still an incident.
Service requests (8)
- New starter needs an account, a laptop and a mailbox: a standard onboarding item.
- Add a user to a shared mailbox: a standard access change, normally approved by the mailbox owner.
- Install an approved application: a catalogue item with a known procedure.
- Access to a SharePoint site: request with approval from the site owner.
- Replace a worn keyboard or mouse: a standard hardware request.
- Increase a mailbox or OneDrive quota: a standard change within agreed limits.
- Leaver: disable the account and collect equipment: a standard offboarding request, often triggered by HR.
- "How do I set up my email on my phone?": a request for information. Answer it, and add the answer to the knowledge base.
Borderline cases (4)
- Forgotten password: a service request when the standard reset works. It becomes an incident if the reset itself fails, or if many users cannot reset at once.
- Locked-out account: one unlock is a request. Repeated lock-outs with no obvious cause are an incident, and usually point to a problem record (for example an old saved password on a phone).
- "My laptop is slow": an incident if it has become slower than before. An exception request that needs approval if the user wants a faster machine than the standard one.
- Software install fails with an error: the install is a request. The error is an incident raised against it, so both clocks are honest.
How the handling flow differs
Use the same order of points when you document both flows, so staff can compare them.
Incident flow
- Trigger: something stopped working or got worse.
- Aim: restore the service. A workaround counts as restoring.
- Priority: set from impact and urgency. See severity vs priority in IT incidents and IT support SLA priority levels P1 to P4.
- Approval: none to start work. Emergency changes to fix it follow your change rules.
- Target: response and resolution time by priority.
- Escalation: up the support levels, then to vendors, and to major incident handling if the impact is wide (see major incident management).
- Closure: the user confirms service is restored. Repeats feed problem management.
Service request flow
- Trigger: a user picks an item from the catalogue or sends a standard form.
- Aim: deliver the item exactly as agreed.
- Priority: usually a single agreed delivery time per catalogue item, not an impact and urgency score. Urgent exceptions are decided by a manager, not by the user selecting "high".
- Approval: defined per item (manager, data owner, security). No approval is the exception, not the default.
- Target: fulfilment time per item, for example "new starter set-up ready by the day before the start date".
- Escalation: only when the approval or fulfilment is late.
- Closure: item delivered, user confirms, approvals and actions are on the record.
Set it up in your ticketing tool
- Make ticket type a required field with three values: incident, service request, and change request. A problem is a separate record linked to incidents, not a fourth choice on the form.
- Build request forms from your catalogue with the required fields (who, what, start date, approver) so staff do not chase details.
- Give each catalogue item an owner, an approver and a delivery time.
- Run two SLA clocks: restore time for incidents, fulfilment time for requests. The L1, L2 and L3 support levels can use the same queue, but the clocks must differ.
- Allow reclassification, but require a reason and keep the history. Never delete and re-create a ticket.
- Put the 20 examples above into the knowledge base so the service desk classifies the same way every time.
Common mistakes
- Treating every ticket as an incident. Routine requests then get emergency priority and real outages are lost in the noise. Fix: separate types and separate clocks.
- Letting users choose priority on a request form. Everyone picks "high". Fix: delivery time comes from the catalogue item; exceptions go through a manager.
- Calling a broken thing a request because the user said "please". Fix: ask the first decision question every time.
- No approval path. Access requests then get done by whoever answers first. Fix: name an approver per item.
- Open text boxes instead of forms. Staff spend the first reply asking for missing details. Fix: required fields per item.
- Silently changing the type. Reporting becomes unreliable and the user is confused. Fix: reclassify with a reason and tell the user.
How to check it worked
- Once a month, read 20 random closed tickets. For each one, ask the three questions and compare with the recorded type.
- Count how many tickets were reclassified. A high number means the form or the examples need work.
- Confirm every closed request names a catalogue item and an approver where one is required.
- Look at fulfilment times by item. Items that are always late need a new target or more capacity, not more reminders.
- Search request tickets for words such as "not working", "error" and "down". Each hit is a possible misclassified incident.
FAQ
What is the difference between a service request and an incident in ServiceNow?
In ServiceNow, as in any ticketing tool, the test is the same: if a service that worked is now broken or degraded, raise an incident; if the user is asking for a catalogued item, raise a request. Use separate record types and separate SLA clocks.
Is a password reset a service request or an incident?
A normal password reset is a service request, because it is a standard action users are entitled to. If the reset process itself is broken, or many users are locked out at once, it is an incident.
What is the difference between a service request and a change request?
A service request asks for something already in the catalogue, with a known procedure, such as access or a standard install. A change request asks to modify the environment, such as a new firewall rule or a new system, and needs assessment and approval before the work starts.
What is the SLA for a service request?
It is usually a fulfilment time for each catalogue item, agreed in advance, rather than a restore time based on impact. For how targets are written, see what an SLA means in IT support.
Can you give examples of incident vs service request?
Yes. The 20 examples above cover broken services (incidents), standard asks (service requests) and four borderline cases.
If you want a service desk that already separates incidents from requests and reports on both, see our 24/7 help desk IT support.
Share:
Ready to take action?
Turn these insights into a roadmap for your business.
Book a 15-minute no-obligation consultation with our APAC IT experts. We'll review your current setup and provide a tailored IT roadmap within 24 hours.
Related services
Free Checklist
10 Critical Checks Before Expanding IT to Greater China
PIPL compliance, network segmentation, bilingual helpdesk setup, and more — everything your IT team needs before Day 1 in China.
Request the checklist →📬 Monthly Asia IT Insights
China compliance updates, cybersecurity alerts, and IT tips for APAC teams — once a month.
No spam. Unsubscribe anytime.
Related Articles
Oct 30, 2026
Incident Management Process: The Lifecycle from Report to Closure, with Roles and Time Limits
Oct 30, 2026
Desktop Support Scope: What L1 and L2 Desktop Support Should Cover
Oct 30, 2026
IT Help Desk Outsourcing Guide: Scope, SLAs, Seat Sizing and Go-Live Steps