How to Use Gemini to Turn Wireless Controller Exports Into a Weekly Multi-Site Health Digest
A practical workflow for using Gemini to compress weekly wireless controller exports across dozens of sites into a ranked health digest, how it compares with controller dashboards and managed wireless reporting, and where a weekly digest is not enough.
Published
The short answer: Your wireless controller already recorded the problem at Branch 14 — the reboots, the channel changes, the failed associations — a week before anyone complained. Gemini's job is to compress that export into a ranked one-page wireless health digest naming the three sites that need attention this week and why. It is a reporting layer on data you already own, not a monitoring system, and it does not replace real-time alerting.
A 26-store retail group runs Ubiquiti UniFi across every site, with one network manager covering all of them from head office. On a Thursday afternoon the Branch 14 store manager calls: the stockroom handhelds keep dropping mid-scan, it has been going on for "a couple of weeks," and could someone please come and look.
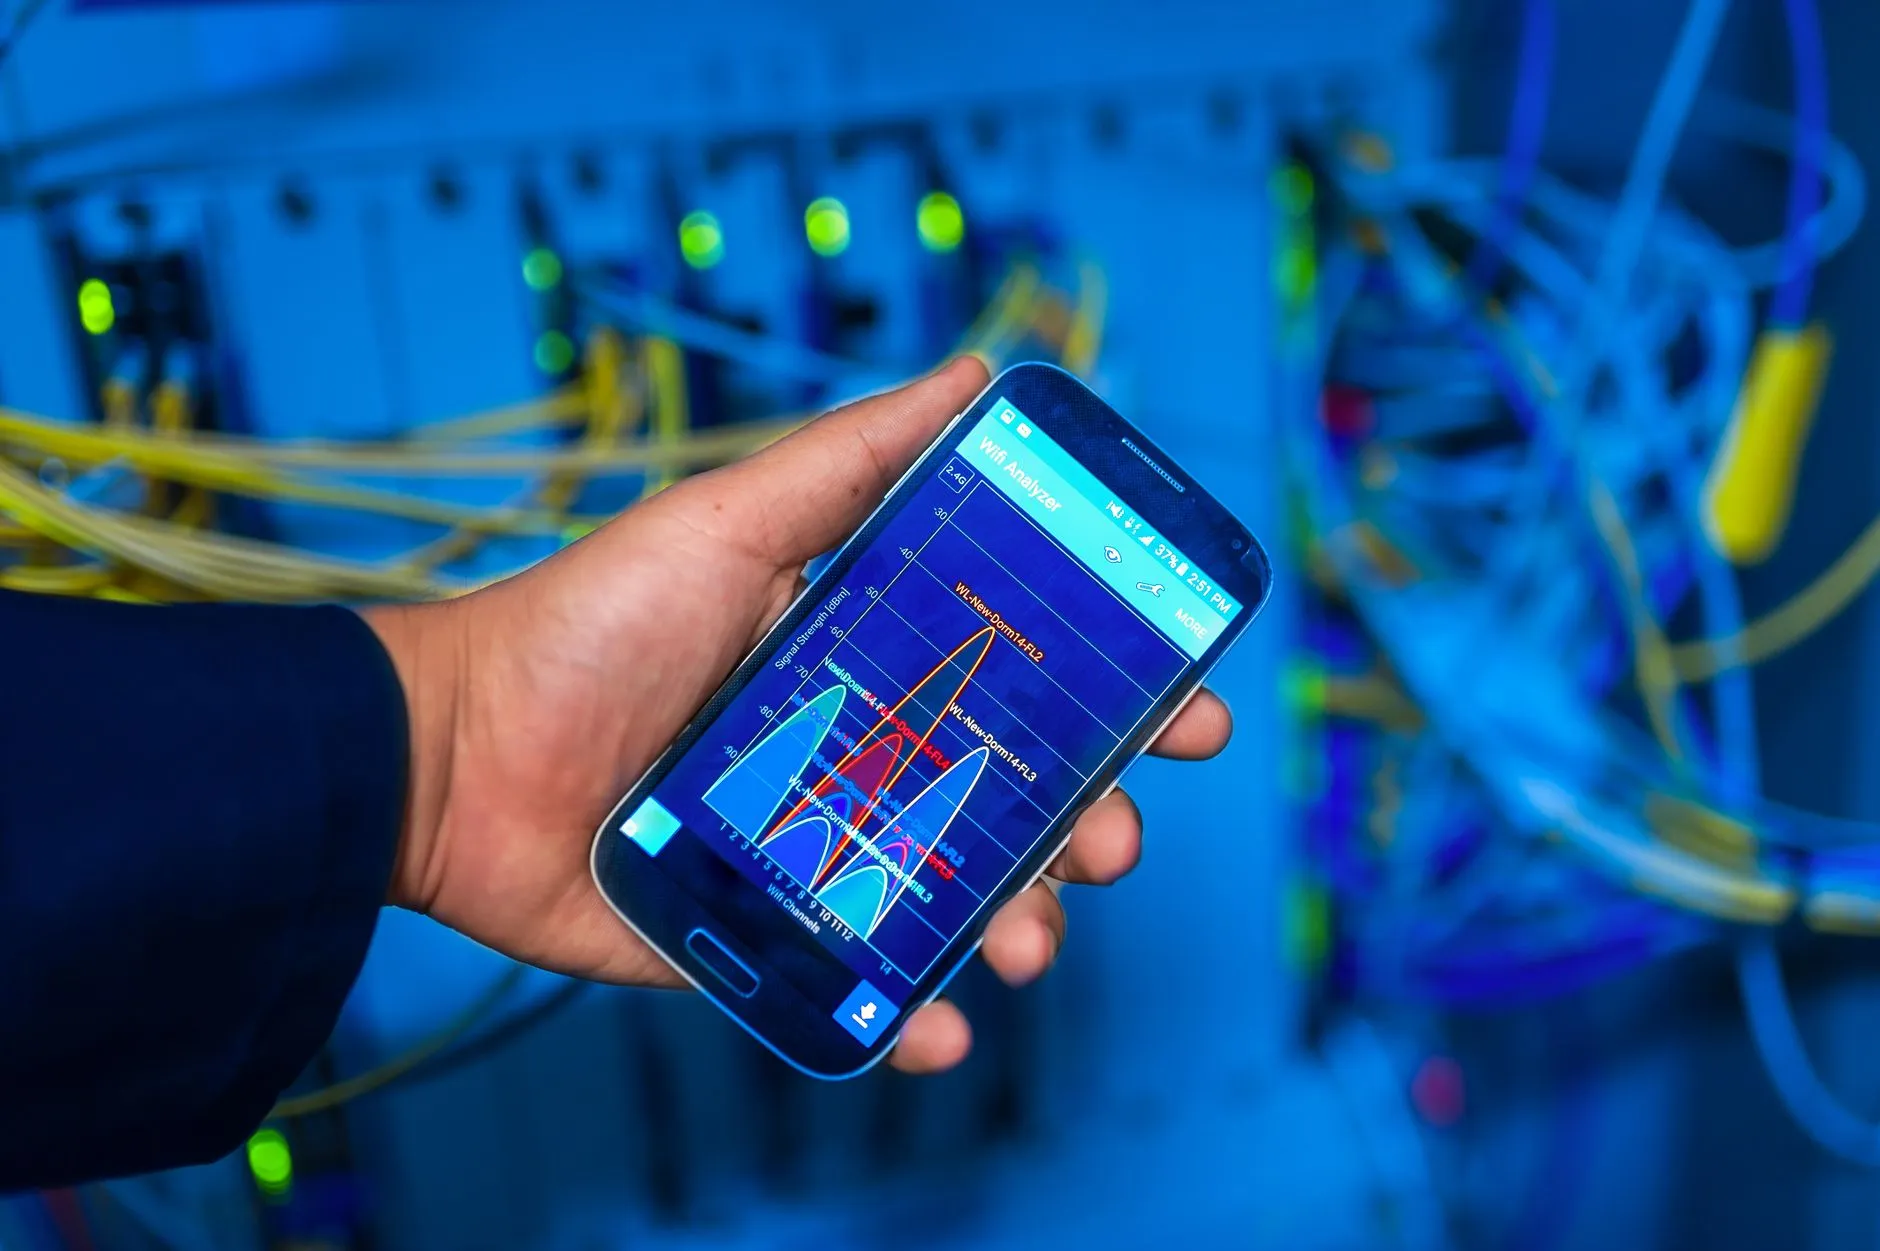
He opens the UniFi Network Application, filters to Branch 14, and finds it in four minutes. One access point — the one mounted near the stockroom roller door — has rebooted eleven times in fifteen days. Two of those reboots are on the same evening. The neighbouring AP has been changing channels repeatedly, which on a 5 GHz radio near an external wall usually means DFS radar detection.
None of this was hidden. The controller recorded every one of those events as it happened, and it is all sitting in the same dashboard he just opened. The reason nobody saw it is that Branch 14 is one of twenty-six sites, each generating hundreds of events a week, and there is no version of a working week in which one person reads twenty-six event logs looking for a pattern that has not yet produced a complaint.
That is the actual gap. Not missing data — unread data.
Why a Wireless Problem at Branch 14 Surfaces as a Complaint, Not an Alert
Controller alerting is built around state: an access point is up, or it is down. If it disconnects, you get a notification. That works, and it catches the failures that are already outages.
What it does not catch is degradation, because degradation has no state to cross. An access point that reboots every thirty-six hours is, at any instant you look at it, online. A radio that keeps moving channels because of DFS hits is behaving exactly as designed. A site where average client signal strength has drifted down eight dBm over two months because someone stacked pallets against a wall never triggers anything at all.
So the three categories of wireless problem that actually generate helpdesk tickets — the flapping access point, the site with quietly worsening coverage, the one band that congests at 2pm every weekday — are precisely the three that no threshold alert fires on.
Then multiply by site count. Twenty-six locations, each with four to twelve access points, each generating association events, roaming events, DHCP failures, channel changes and firmware notices. A weekly export across the estate is easily several thousand rows. Read end to end, it would take an afternoon. Nobody has the afternoon, so it does not get read, so the first genuine signal is a phone call from a store manager who has been living with the problem for a fortnight.
What Gemini Can Actually Do With a Controller Export
Gemini is Google's assistant family, usable through the Gemini app, Google AI Studio, and Gemini in Google Workspace, where it can work directly on a file in Drive or a sheet in Google Sheets. The capability that matters here is a large context window — a long structured export can be read in one pass rather than in chunks — together with competent handling of tabular data. Exact limits vary by model and tier and change often, so check current documentation before designing a process around a specific file size.
Two caveats before anything else. Gemini does not connect to UniFi or Meraki; nothing described here is an integration. You export, and it reads what you exported. And it has no knowledge of your network beyond what is in that file, so a site name it has never seen is just a string.
Turning a raw event export into a ranked, readable digest
The useful output is not a summary of the whole export. It is a ranking. Given a week of events across twenty-six sites, the question worth asking is: which three sites are worse this week than last, which specific access points are responsible, and what does the evidence say.
That is a question about counting, grouping and comparison — sorting events by site and device, spotting that AP-14-03 accounts for eleven of the estate's nineteen unexpected reboots, noticing that Branch 22's failed-association count tripled on Monday morning. A model handles that reliably when the export contains the columns to do it with, and it writes the result in sentences a store operations manager can read without knowing what DFS means.
Spotting the slow-building pattern before it becomes an outage
The second thing worth asking for is trend, and trend needs more than one week of input. Keep the last eight exports and ask for the comparison explicitly: which sites have a rising reboot count over eight weeks, which have declining average signal strength, which show a repeating time-of-day pattern.
That is where the Branch 14 story would have broken differently. Eleven reboots in fifteen days is invisible in a single week's log — it is one or two lines, indistinguishable from noise. Across eight weeks of exports it is an obvious upward line on one device, and it reads as "AP-14-03 has rebooted in seven of the last eight weeks, and the count is rising" — which is a site visit you schedule, not an emergency you react to.
A Practical Workflow — From a Weekly Export to a Digest Ops Actually Reads
1. Fix what "the export" means before automating anything. Decide the columns once: timestamp, site, device name, device MAC, event type, severity, and — if your platform exposes them — client count and average signal. Cisco Meraki's dashboard offers scheduled summary reports and a REST API; Ubiquiti UniFi exposes its own API and CSV downloads from several views. Either route is fine. What is not fine is a different shape of file each week, because then this week's digest is not comparable to last week's.
2. Name your sites the way your business names them. If the controller calls it "UK-STR-014-AP03" and the store is "Branch 14," every digest needs translating by its reader. Either fix the naming in the controller or include a mapping table in the prompt. This is the single change that most affects whether anyone reads the output.
3. Write one prompt and then freeze it. Something like: *"Attached is this week's wireless event export across 26 retail sites. Rank the five sites needing attention, worst first. For each: the site, the specific access point, the event counts that justify it, and one sentence on the likely cause. Separately list any access point appearing in the top five for a third consecutive week. Ignore routine client roaming. If a site has nothing notable, do not mention it. No preamble."* The exact wording matters less than the fact that it never changes — a digest is only useful if this week's is comparable to last week's.
4. Attach the last eight exports, not just this week's. Trend is most of the value, and trend needs history. Keep them in one Drive folder with dated filenames so the set is easy to re-attach.
5. Require the counts inline. "Branch 22 is showing instability" is a sentence you cannot act on. "Branch 22: AP-22-01 recorded 47 failed associations on Monday between 09:00 and 11:00, against a site weekly average of 6" tells you where to look and roughly what window to look at.
6. Verify the top item against the controller before you send it. Every week, one item: open the controller and confirm the number is real. It takes two minutes, and it is the difference between a digest people trust and one that gets quietly ignored after the second wrong claim.
7. Close the loop by recording what was done. Each item gets one of three outcomes: fixed, scheduled, or watching. Next week's digest opens with last week's "watching" list. Without this, the digest reports the same access point for six weeks running and the reader learns to skip it.
An AI-Summarized Digest vs Raw Controller Dashboards vs a Managed Wireless Provider's Reporting
- A Gemini-summarized weekly digest. Cheap, quick to set up, and shaped exactly to your estate and your site names. It reads data you already own and turns it into something a non-network person can act on. It is retrospective by definition, only as good as the export, produces nothing contractual, and depends on somebody actually running the export each week. Correct use: the weekly review that makes slow degradation visible.
- The controller's own dashboards and alerts. Authoritative, live, and the only one of the three that can tell you something is happening right now. It also holds the full detail — per-client history, RF data, packet-level tooling — that any summary necessarily discards. What it does not do is rank twenty-six sites against each other or surface a trend across two months, because it is built to answer "what is happening at this site" rather than "where should I spend Thursday." Correct use: real-time alerting, and the source of truth you verify against.
- A managed wireless provider's reporting. Comes with someone whose job is to read it, act on it, and carry the consequence if they do not — which is the part neither of the others supplies. It typically includes proactive firmware management, RF tuning, hardware replacement under contract, and round-the-clock backline escalation, and it produces reporting you can hold a vendor to. It costs money, and its report is built to the provider's template rather than yours. Correct use: when wireless is business-critical across enough sites that reading a digest is not the same thing as having the capacity to act on it.
Where a Weekly Digest Is Not Enough
A real outage needs real-time alerting. If an access point dies at 09:40 on Monday, a Friday digest is not the mechanism. Keep your controller alerting configured and routed to someone who will see it, and treat the digest as strictly additive.
Physical failures need a person at the site. A failing PoE injector, a damaged antenna, a cable pinched behind a shelving unit, an access point unplugged so a display could be charged — none of these is fixed by better reporting. The digest's job is to tell you which site to send someone to, and that is where its job ends.
The export cannot show what it never recorded. Controller-side data describes the infrastructure. It does not describe the client's experience — the handheld with an outdated wireless driver, the interference source that degrades performance without generating an event, the roaming behaviour of one badly behaved device model. When the digest is clean and users are still unhappy, the answer is a site survey, not a longer prompt.
Getting This Right — Network Data Sensitivity, Alert Routing, and When to Bring in IT
Decide what leaves your network before the first export. A wireless event export can contain client MAC addresses, device hostnames with employee names in them, and effectively a map of your physical estate. Strip what you do not need — most digests work perfectly well with client identifiers removed entirely — and make that call once, at company level, rather than per person per week.
Know which tier you are using and what its terms are. Consumer and enterprise AI tiers differ in how data is retained and whether it may be used for training, and those terms change. If operational network data is going in, use the tier your organisation has actually reviewed.
Give every digest item an owner and a next action. The failure mode is not a bad digest; it is a good digest that gets read, nodded at, and forgotten. Five items, each with a name against it, closed out the following week.
Working out where an assistant genuinely helps in network operations, and building prompts and routing that survive a bad week, is AI+ Support work. The wireless estate underneath it — multi-site cloud management, proactive firmware and RF tuning, round-the-clock backline maintenance — is managed wireless network territory, delivered through the same IT support desk that takes the call from Branch 14. If your problem is coverage rather than trend, the pre-deployment side is covered in our write-up on interpreting Wi-Fi survey data with Gemini, and the same weekly-export technique applied to voice in analysing cloud PBX call logs.
Frequently Asked Questions
Does this replace real-time wireless alerting?
No, and it is important not to let it drift into that role. Your controller's alerting is what tells you an access point dropped at 09:40. The digest looks backwards across a week to find the problems that never crossed an alert threshold — the AP rebooting every other day, the site whose signal quality has drifted, the band that congests every weekday afternoon. Keep both, and keep them clearly separated in people's minds.
Which wireless platforms does this work with?
Any platform that can export structured event or statistics data, which in practice means all the major ones. Cisco Meraki offers scheduled summary reports and a REST API; Ubiquiti UniFi has its own API and CSV downloads; Aruba, Ruckus and others provide equivalent export or API routes. The AI side is platform-agnostic because it never touches the platform. What matters is that the export has consistent columns week to week, not which vendor produced it.
Can it predict an access point failure before it happens?
Not in any rigorous sense, and you should be sceptical of anyone claiming otherwise about this class of data. What it does is make a trend visible early — an access point that has rebooted in seven of the last eight weeks, with the count rising — which is often enough to schedule a replacement before the device fails completely. That is early warning from counting, not prediction from modelling. It cannot see a failing power supply or water ingress that has not yet produced an event.
How is this different from the report our managed wireless vendor already sends?
Mostly in who acts on it. A vendor report is built to their template, arrives on their schedule, and covers what they have contracted to cover — but it comes with an engineer who is obliged to do something about what is in it. A self-built digest is shaped to your sites and your naming, costs nothing but the time to run it, and is strictly a reporting layer: it creates no obligation on anyone. If you already have a managed wireless contract, the more useful question is usually whether your provider's report contains the ranking and trend you need, and asking them to add it.
Should we do this monthly instead of weekly?
Weekly is better for the degradation cases, because a fortnight of a flapping access point is roughly when users start complaining, and a month is well past it. Monthly works if your estate is small and stable, but you lose the ability to see "third week running," which is the single most useful signal the digest produces.
Share:
Ready to take action?
Turn these insights into a roadmap for your business.
Book a 15-minute no-obligation consultation with our APAC IT experts. We'll review your current setup and provide a tailored IT roadmap within 24 hours.
Free Checklist
10 Critical Checks Before Expanding IT to Greater China
PIPL compliance, network segmentation, bilingual helpdesk setup, and more — everything your IT team needs before Day 1 in China.
Request the checklist →📬 Monthly Asia IT Insights
China compliance updates, cybersecurity alerts, and IT tips for APAC teams — once a month.
No spam. Unsubscribe anytime.